Learning
Everything I've written, in one place
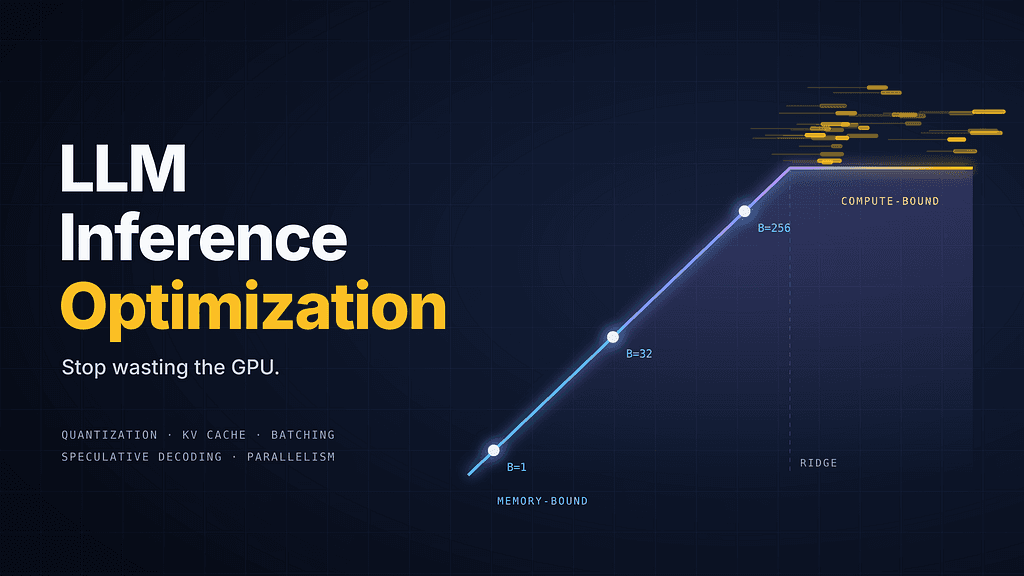
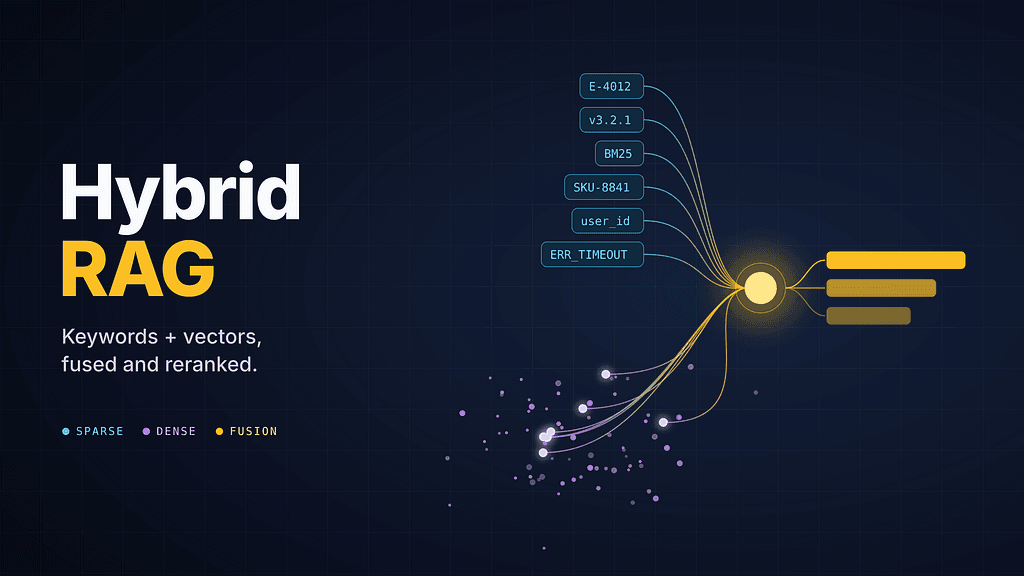
Articles on LLM systems, retrieval, AI security and backend engineering — written while learning them the hard way. Posts are pulled from Medium and refresh automatically.
Articles on LLM systems, retrieval, AI security and backend engineering — written while learning them the hard way. Posts are pulled from Medium and refresh automatically.